Why start from public listings
Most companies want to be found. They list themselves in directories, join associations, exhibit at trade fairs and publish their details on their own website. That makes public listings the most honest starting point for a B2B list: the company chose to be there, and you can always show where you found it.
A list you collect yourself is also more relevant than one you rent. You pick the niche and the region, and you know what every row means. The trade-off is effort. This guide keeps that effort small and the result clean.
Where company data sits in the open
Good sources share three traits: the companies are grouped by something you care about, each entry has a website or contact detail, and the list is maintained.
- Trade associations and member lists. Often grouped by sector and region, and members are real, active businesses.
- Trade fair exhibitor lists. Companies that pay to exhibit are actively looking for customers. Lists usually include a website and a short description.
- Industry directories. Sector portals, supplier finders and marketplace listings, often with category filters.
- Certification and quality registers. Lists of certified electricians, accredited labs or approved suppliers. Useful when certification matters to your offer.
- Local business pages. Municipal or regional business directories and business park websites, handy for service businesses working one area.
- Company websites. The "about" and "contact" pages give you the details the company itself wants you to use.
Official business registers are useful to check a company exists and what it does. Many of them have their own terms for reuse, so read those before you copy anything in bulk.
Respect the terms and robots.txt
Public does not mean free for any use. Before you collect from a site, check two things.
- The terms of use. Many directories forbid automated collection or reuse of their listings. If they do, do not scrape them. Use the listing to find companies and visit their own sites instead.
- robots.txt. Open
example.com/robots.txt. It tells automated tools which paths the owner does not want visited. It is not a law, but ignoring it is a clear signal you are not welcome.
Collect at a human pace. Opening one page, saving its list and moving to the next is very different from firing thousands of requests at a server. Keep only what you need for business contact: company name, website, city, phone, a generic email. Skip private details. The GDPR guide explains why the source and date of every record matter.
Collect with a browser extension
Browser extensions such as Instant Data Scraper read the page you have open, detect a repeating list or table and turn it into rows you can save as CSV or Excel. They work on the page in your own browser, so you see exactly what you collect.
A typical session looks like this:
- Add the extension to your browser from its official store page.
- Open the listing page, for example an exhibitor list filtered on your sector.
- Start the extension. It highlights the table it thinks you want. If it picked the wrong block, try the next suggestion.
- If the list spans several pages, point it at the "next" button and let it walk through them at a gentle pace.
- Export to CSV or Excel and name the file after the source, like
exhibitors-tradefair-2026.csv.
Or paste the page into Riftjaw
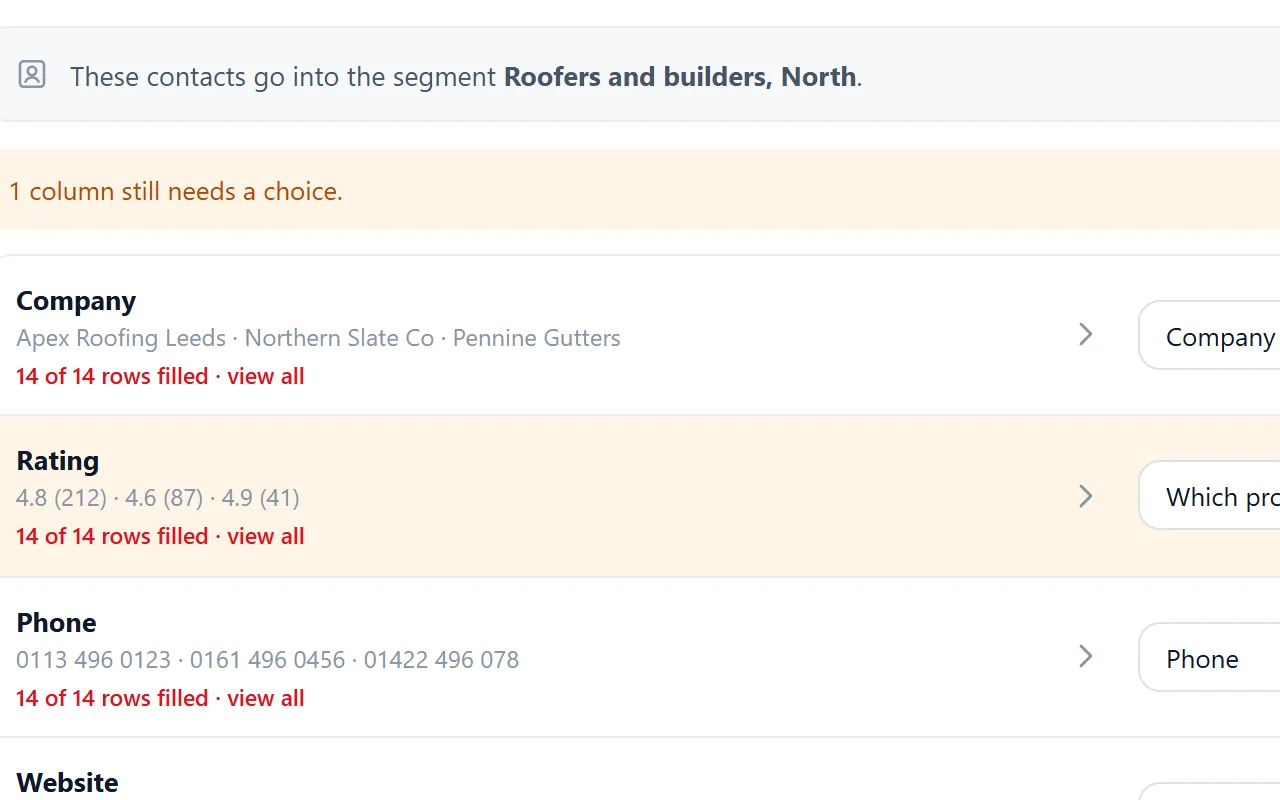
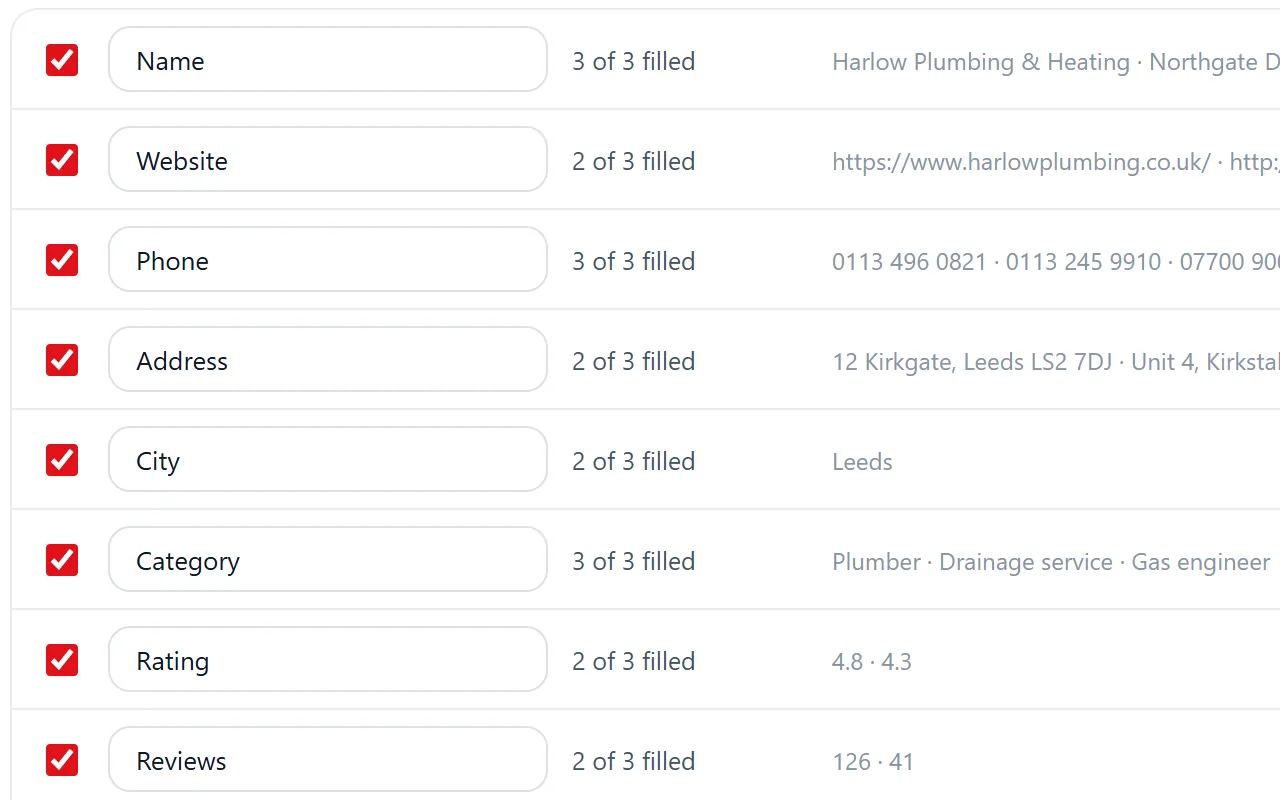
No extension, or a page the extension does not read well? Use paste and collect. Copy the HTML of the page you have open, paste it into the dashboard, pick the repeating blocks you need and turn them into rows. Those rows go straight to the import screen.
Riftjaw does not crawl the web itself. You supply the page, which keeps you in control of what you collect and where it came from.
Clean before you import
Five minutes of cleaning saves an hour of fixing records later. Open the file and check:
- Columns. Delete columns that are only layout, like image links or "view profile" buttons.
- Websites. Make sure the website column holds the company's own site, not a link back to the directory profile.
- Empty rows. Remove rows without a company name. Scrapers often pick up headers and ads.
- Mixed fields. A column like "Springfield, +44 20 7946 0142" is two fields. Split it now or map it to a note.
- Source. Add a column with the source and the date you collected it, if the file does not say so already.
Import into your database
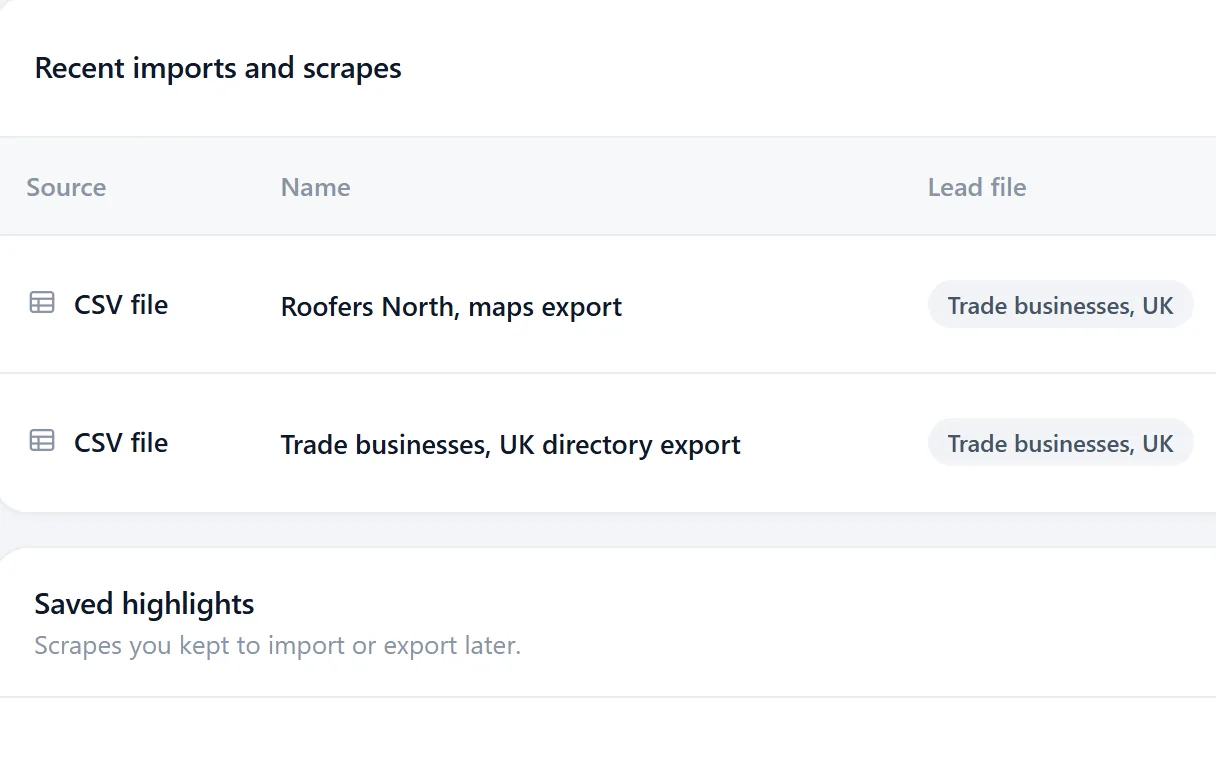
In the dashboard, open Import / Scrape and start a new import. Pick the segment the companies go into, or create one on the spot, such as "Plumbers North". Three steps follow: match the columns, check the import and publish the records.
No email column? Tick a few prefixes and derive addresses from the domain while importing. Then read the database guide to keep the list useful after week one.